AWS Glue
AWS's service for finding, describing and cleaning up data, with no servers to run.
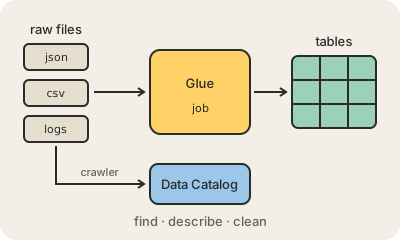
AWS Glue is the AWS service for ETL: taking data from where it lands, cleaning and reshaping it, and putting it where people can analyze it. A typical case: every night an app drops thousands of JSON files into Amazon S3, and a Glue job reads them, removes duplicates, fixes dates, joins them with a customer table and writes the result as Parquet files ready for queries.
Its second half is the Glue Data Catalog, a register of every dataset: where the files live, what columns they have and of what type. A crawler can fill it for you by opening the files and guessing their structure. The catalog is what lets Amazon Athena or Amazon Redshift query a folder of files in S3 as if it were a table.
Glue is serverless: you write the transformation (in Python or SQL on top of Apache Spark, or by dragging boxes in a visual editor), say when it should run, and AWS spins up the machines for the duration of the job. You pay for the processing time used, not for idle clusters. That makes it the glue, as the name says, of many data lakes built on AWS.
Keep in mind
- Runs ETL jobs on Apache Spark without you managing a cluster.
- The Data Catalog describes datasets so Athena and Redshift can query them as tables.
- Crawlers inspect files and infer their columns and types automatically.
- Billed by processing time while jobs run; nothing runs between jobs.