Data cleaning
Fixing errors, gaps and duplicates in data before anyone trusts it.
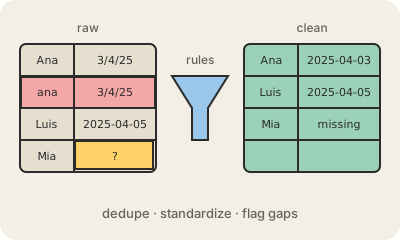
Data cleaning is the work of finding and fixing problems in a dataset so it can be used safely. Real data is messy: the same customer typed twice with slightly different names, dates written as 03/04/2025 in one system and 2025-04-03 in another, an age of 250, a blank email, prices with a comma in one country and a dot in another.
Typical steps are removing duplicates, standardizing formats (dates, currencies, country names), handling missing values (fill them, flag them or drop the row), catching values that cannot be true, and checking that references match, for example that every order belongs to a customer who exists. Each decision is a judgment call, so good teams write the rules down and run them as code instead of fixing cells by hand.
It is famously the least glamorous and most time-consuming part of working with data, and also one of the most important. A dashboard or a machine learning model is only as good as the data it is fed; "garbage in, garbage out" is the oldest saying in the field. In a pipeline, cleaning usually happens in the transform step of ETL, and the checks keep running every time new data arrives.
Keep in mind
- Fixes duplicates, inconsistent formats, missing values and impossible numbers.
- Every rule is a decision; write it down and automate it.
- Usually part of the transform step in a data pipeline.
- Garbage in, garbage out: reports and AI models inherit every error.