Data quality
How far data can be trusted for the job it is used for.
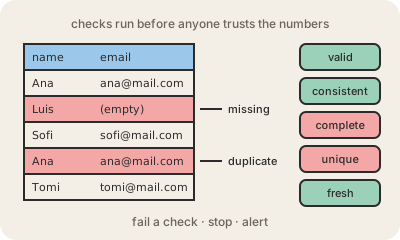
Data quality is the degree to which data is fit for its purpose: correct, complete and current enough that decisions built on it are sound. A customer table where a third of the emails are missing, the same person appears three times and half the addresses are from 2015 has poor quality, even if the database itself works perfectly.
It is usually broken into a few dimensions. Completeness: are required fields filled in? Validity: do values follow the rules, like a date that is a real date or an age that is not negative? Uniqueness: is each thing recorded once? Consistency: does the same fact match across systems? Timeliness: did today's data actually arrive today? Accuracy: does it match reality?
Teams protect quality with automated checks that run every time data moves through a pipeline: if yesterday's orders table suddenly has zero rows or a column full of nulls, the check fails and someone is alerted before a wrong number reaches a dashboard. Tools like dbt tests or Great Expectations do this. Fixing data downstream, through data cleaning, works, but fixing the form or system that produces the bad data is cheaper.
Keep in mind
- Means data is fit for its use: correct, complete and current enough.
- Common dimensions: completeness, validity, uniqueness, consistency, timeliness, accuracy.
- Automated checks in pipelines catch problems before they reach reports.
- Fixing the source beats cleaning the same errors again and again.