Data partitioning
Splitting a huge table into pieces by a key, so queries only touch what they need.
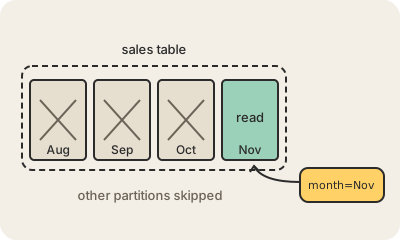
Data partitioning means splitting one large table or dataset into smaller pieces, called partitions, according to a column such as date, country or customer ID. To the person writing SQL it still looks like one table, but under the hood each partition is stored separately.
The main payoff is partition pruning. If a sales table is partitioned by month and you ask for November, the database reads only the November partition and skips the other years of data entirely. In a data lake the same idea shows up as folders like year=2026/month=11/ full of Parquet files, and engines like Spark or Athena read only the folders that match. Partitions also make housekeeping cheap: deleting a month of old data is dropping one partition instead of hunting for millions of rows.
When partitions are spread across different servers, it is called sharding, and it is how very large apps spread load beyond what one machine can handle. The hard part is picking the key. Partition by something queries rarely filter on and you get no benefit; pick a key where one value gets most of the traffic, such as one giant customer, and you create a hot partition that becomes the bottleneck while the others sit idle.
Keep in mind
- Splits a table by a key such as date or region; queries still see one table.
- Partition pruning lets a query skip every partition it does not need.
- Sharding is partitioning across several servers.
- A poorly chosen key gives no speedup or creates a hot partition.
Go deeper
- Partition (database) on Wikipedia
- Table partitioning (PostgreSQL docs)
- Shard (database architecture) on Wikipedia