Amazon Textract
An AWS service that reads scanned documents and pulls out text, forms and tables.
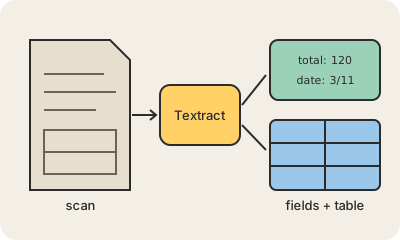
Amazon Textract takes an image or a PDF of a document, such as a scanned form, a receipt or a bank statement, and returns its contents as data a program can use. At the simplest level it does OCR, optical character recognition: it finds the typed and handwritten words and where they sit on the page.
What sets it apart from plain OCR is that it understands layout. It can read a form and pair each label with its value ("Name: Ana Pérez"), rebuild a table row by row and cell by cell, and answer queries like "what is the policy number?" even when the field is in a different spot on every document. Specialized operations handle invoices and receipts, and identity documents like U.S. driver's licenses and passports.
Typical uses are automating paperwork: loading invoices into accounting systems, processing insurance claims or loan applications, or making archives of scanned files searchable. Each result comes with a confidence score, so a common pattern is to let high-confidence fields through automatically and send the doubtful ones to a person to review.
Keep in mind
- Extracts typed and handwritten text from images and PDFs.
- Understands forms (label and value) and tables, not just loose words.
- Queries let you ask for a specific field by question.
- Confidence scores help decide what still needs human review.
Go deeper
- What is Amazon Textract? (official docs)
- Amazon Textract product page
- Optical character recognition on Wikipedia