Model parameters
The billions of numbers a model learns in training; '70B' means 70 billion of them.
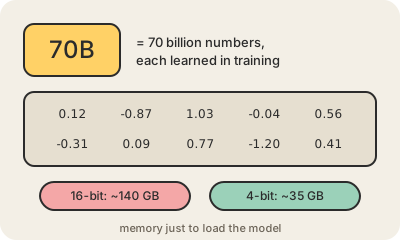
A neural network is, underneath, a huge collection of numbers. During training each of those numbers is adjusted again and again until the model gets good at its task. Those learned numbers are the parameters, also called weights. They are the model: when people 'download a model', they are downloading a file full of them.
When you see a name like 'Llama 70B' or hear 'a 7-billion-parameter model', the number is how many parameters it has: B means billion. In 2020 GPT-3 had 175 billion, which seemed enormous at the time. More parameters give a model more room to store patterns, so bigger models tend to be more capable, but the quality and amount of training data matter just as much, and a well-trained small model can beat a sloppy big one. Many companies no longer publish parameter counts for their top models.
The count also tells you what hardware you need. Each parameter is stored with a certain precision: at 16 bits it takes 2 bytes, so a 70B model needs roughly 140 GB of memory just to load, far more than a laptop has. Quantization stores each number with fewer bits, for example 4, shrinking the same model to roughly 35 GB at a small cost in quality. Some models, called mixture of experts, only use part of their parameters for each word, so they run faster than their total size suggests.
Keep in mind
- Parameters, or weights, are the numbers a model learns in training.
- '70B' means roughly 70 billion parameters.
- Memory needed is about parameters times bytes per parameter.
- Bigger is often more capable, but data and training matter as much.
Go deeper
- Large language model on Wikipedia
- Machine learning glossary: parameter (Google)
- Mixture of experts on Wikipedia